Invoices in.
Proof out.
ExtractaDE reads documents with AI and proves every number: checksums catch what OCR misreads before it reaches your books.
From image to booking data
One continuous run per document. Every stage feeds the next; nothing lands in your books unverified.
Upload
Photo, scan, or a sample document
Extract
Gemini reads 15 fields from the image
Validate
Checksums test IBAN, VAT ID, totals
Export
CSV in German Excel convention
Upload
Photo, scan, or a sample document
Extract
Gemini reads 15 fields from the image
Validate
Checksums test IBAN, VAT ID, totals
Export
CSV in German Excel convention
Measured, not claimed
Field accuracy
168 of 180 fields exact across 12 clean documents
Money fields correct
Net, VAT, gross: every amount exact
Corrupt documents caught
Both planted corruptions flagged before export
Per document
OCR plus extraction end-to-end, local benchmark
Running cost
Per document in on-premise operation
Benchmark 2026-11-16, 14 synthetic documents (12 clean, 2 corrupt). Extraction is a real API call per run. Full benchmark report.
It catches what OCR misreads
Three checks against everything extraction can get wrong. Each one runs before the export.
IBAN checksum
mod-97
A twisted digit stands out even when the account number looks plausible.
VAT ID check digit
ISO 7064 mod 11,10
VAT IDs with a wrong check digit get flagged before they reach a booking.
Totals consistency
|gross - (net + VAT)| <= 0.02
Arithmetic errors in the document itself are made visible.
What OCR read
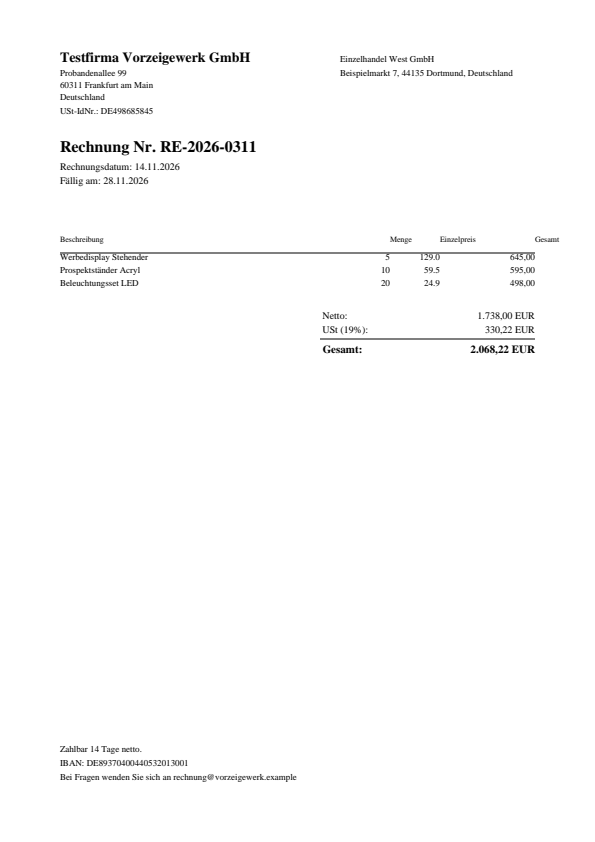
Testfirma Vorzelgewerk GmbH Invoice no. RE-2026-0311 Net: 1,738.00 EUR VAT (19%): 330.22 EUR Total: 2,068.22 EUR IBAN: DE89 3704 0044 0532 0130 01
The IBAN looks plausible. 22 characters, German format, nothing suspicious at a glance.
What the validation layer says
A digit was twisted inside the account number. The document is flagged and exported, never silently passed.
Source: rechnung_13 from the demo corpus, marked corrupt. The check protocol is computed live on this page.
Your documents stay on your server
The on-premise variant runs GLM-OCR directly on your hardware. In the offer, every page image stays in your house.
For this web demo: only the uploaded page image goes to Google for extraction. Validation runs entirely on our server.
| Operating mode | Extraction | Validation | Data protection |
|---|---|---|---|
| On-premise (offer) | GLM-OCR local (0.9B parameters, 315 MB RAM) | local, in-house | pixels never leave your server |
| Cloud demo (this page) | Gemini 3.1 Flash Lite, only the page image | local, on this page's server | only the document image goes to Google |
| Benchmark | AWS Textract reaches 60 to 82% field accuracy on invoices in independent studies | ||